Zipf's Law Text Analyzer
Paste a text to get a rank–frequency chart on log-log axes, the slope, R² and a Zipf fit index, plus the words that appear noticeably more often than Zipf's law predicts.
How the numbers are calculated
- Words: runs of Cyrillic and Latin letters (hyphens and apostrophes inside are kept). Numbers and punctuation are dropped, case is ignored, Russian «ё» is treated as «е».
- Slope and R²: a linear regression on log(rank) vs log(frequency). Only words seen at least twice are used (or the top 50 words if fewer than 10 qualify): the tail of one-off words forms a flat “step” that would distort the slope.
- Index 0–100 = 60% × how close the slope is to −1 (1 at −1, 0 when off by 0.8 or more) + 40% × line fit (1 at R² = 1, 0 at R² ≤ 0.7). 80+ is a close fit, 60–79 moderate, below 60 weak.
- The “Zipf” column is the classic f₁ / rank, where f₁ is the count of the most frequent word; “Deviation” is the difference from it. The “above norm” mark is relative to your text’s own regression line instead, so a shallow or steep slope alone doesn’t turn every word into an outlier: the word is not a stop word, occurs at least 3 times and 1.5× more often than the line predicts. A rank-1 word is also marked when stop words are kept and it still outranks all of them: in natural text the top spots belong to articles, prepositions and conjunctions.
Key facts
Zipf’s law: in natural text a word’s frequency is roughly inversely proportional to its rank, and on a log-log chart this is almost a straight line with a slope near −1. Paste a text and the tool draws the chart, computes slope and R² and gives a fit index. It is statistics, not an AI detector: a short text, a list or mixed languages will deviate.
- Price
- Free
- Sign-up
- Not required
- Processing
- In your browser — nothing is sent to our server
- Input
- Text of 50 words up to 50,000 characters
- Limits
- No sign-up and no request limits; at least 50 words and at most 50,000 characters; estimates are unstable on texts under 300 words
- Output
- The slope and R² of the log-log line, a Zipf fit index from 0 to 100, a top-30 word table with frequencies and stop-word marks, a rank–frequency chart with the ideal line and a list of words more frequent than predicted
- Last updated
See it in action
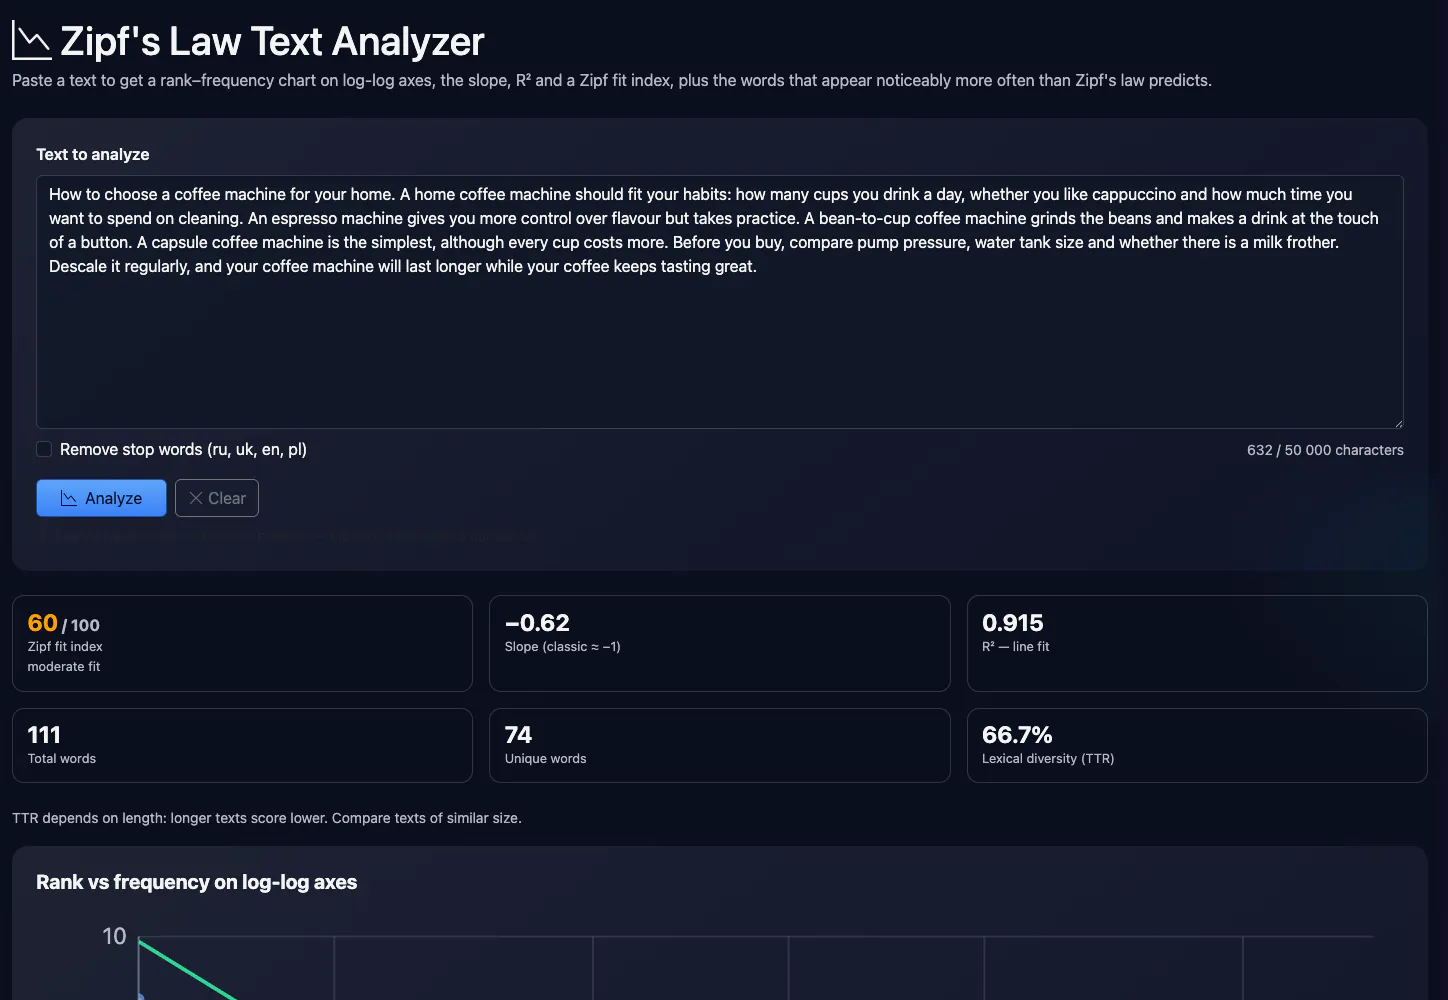
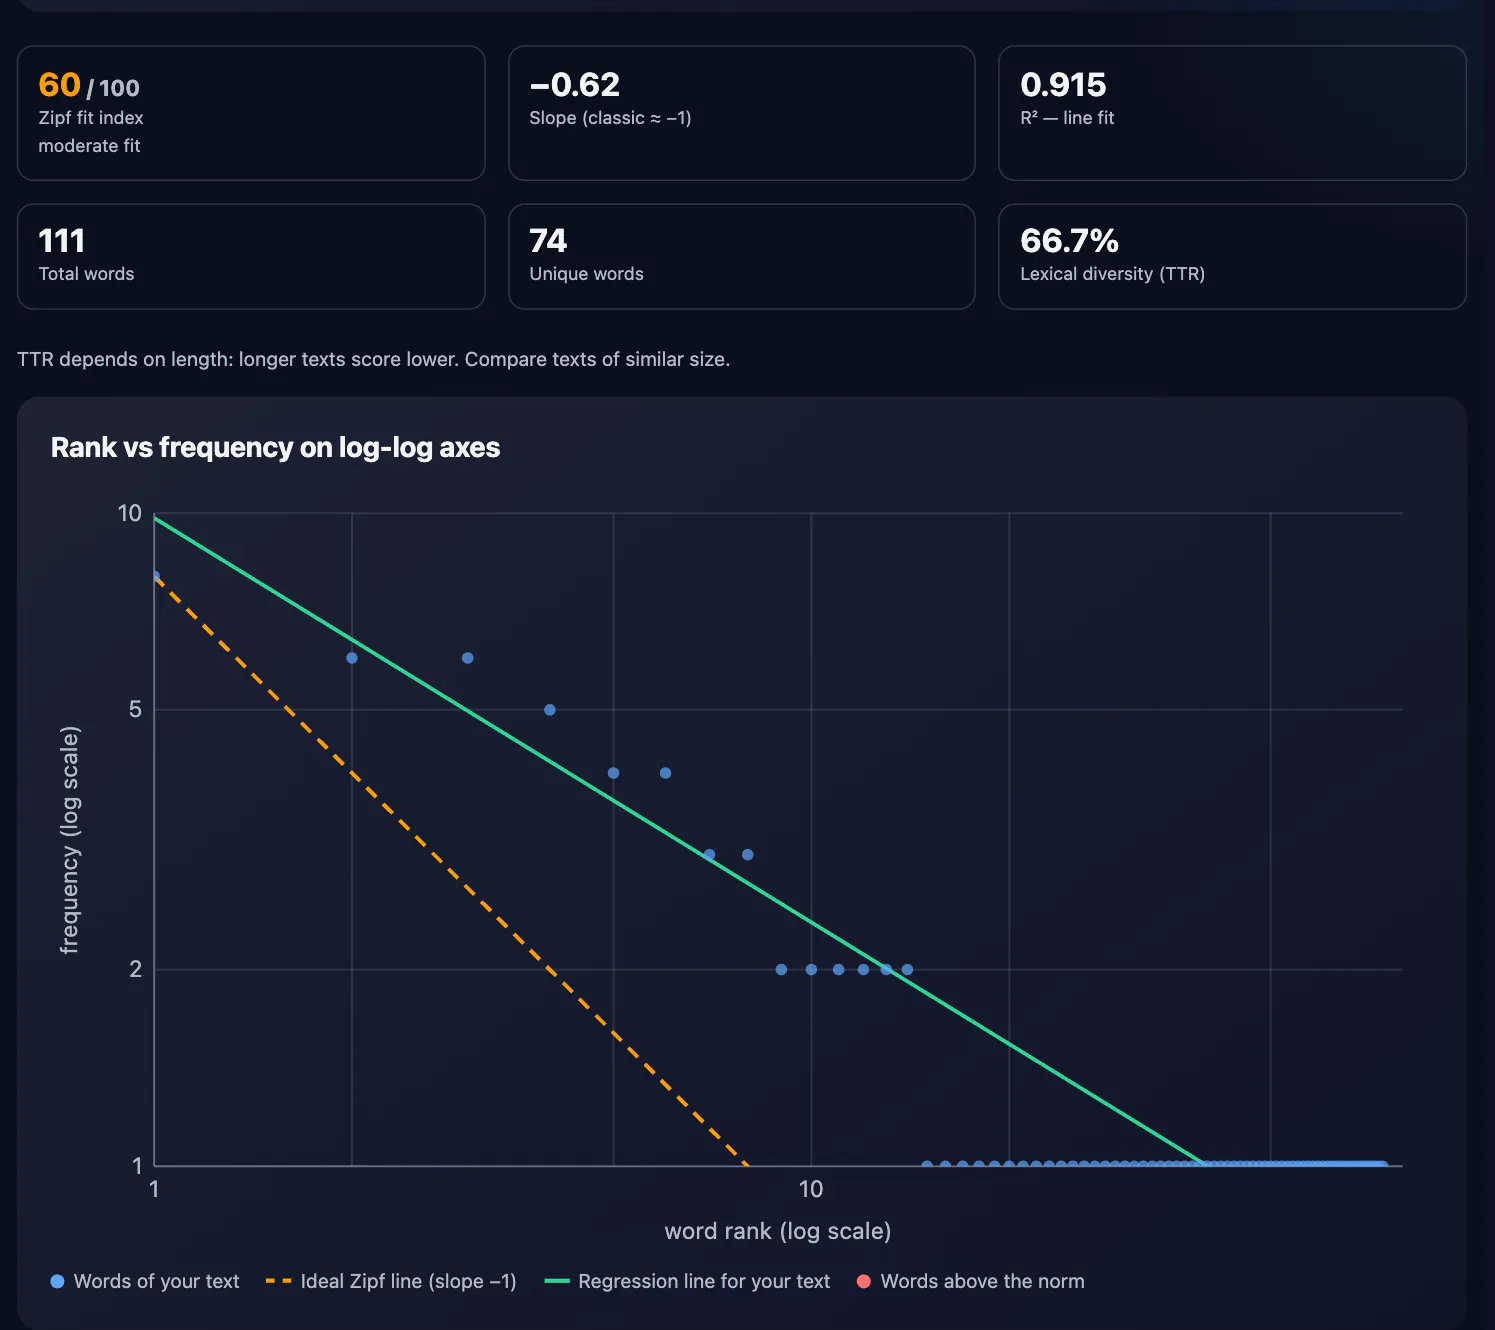
Zipf's Law Text Analysis Online
Check a text against Zipf's law: the tool counts word frequencies, plots rank vs frequency on log-log axes next to the ideal Zipf line, computes the slope and R² of a linear regression and combines them into a 0–100 fit index. Words that appear noticeably more often than the text's own distribution predicts are highlighted, which helps spot keyword stuffing. Runs in your browser, no sign-up.
How to Use
- Paste a text — 300+ words, ideally 1,000+ (up to 50,000 characters)
- Optionally turn on stop-word removal and click “Analyze”
- Review the slope, R², the chart and the highlighted words in the table
FAQ
Who it is for and typical uses
- Copywriters and editors. Find words that occur noticeably more often than expected and replace repetition with synonyms.
- Students and linguists. Draw a rank–frequency chart for your corpus and compute the slope.
- Comparing text versions. See how the index changes after edits or translation.
Honest limitations
- It is not an AI detector. Fitting Zipf’s law proves neither human nor machine authorship.
- Short texts are unreliable. Under 300 words a couple of repeats shift the slope noticeably; you need at least 50 words, ideally a few thousand.
- Lists and mixed languages add noise. Pasted fragments, enumerations and tables sit poorly on a straight line.
- Tokenisation is simple. Words are split on spaces and punctuation with no lemmatisation, so forms of one word count separately.
- Up to 50,000 characters. Longer text is truncated.
Related: keyword density, word counter, readability, AI detector.
PromoPilot vs alternatives: comparison
We compare only what is confirmed on each service's own pages. Where we could not confirm a fact, the cell shows "—".
| Parameter | PromoPilot | Wikipedia: закон Ципфа (справка) |
|---|---|---|
| Rank–frequency chart with slope and R² | ✓ | Explains that a log-log plot shows how closely data follow the law; no tool |
| Fit index 0–100 | ✓ | ✗ |
| Words more frequent than expected | ✓ | ✗ |
| No text sent to a server | ✓ | — |
Scroll the table sideways
Where we are weaker: tokenisation is simple with no lemmatisation, up to 50,000 characters, no file upload or multi-text comparison, and the index is our own scale, not a standard metric.
When to choose PromoPilot: When you want to see the word-frequency distribution of your own text in seconds, spot overused words and judge how natural the text looks. A single index is not enough to judge AI authorship or SEO text quality.
Checked on: . "—" means not confirmed on the official page; terms and prices change, so check the services' own sites.
Zipf's law text analysis: what is actually measured
Zipf's law describes how word frequencies are distributed in natural language. Sort the words of a text by frequency and number them (rank 1 is the most common word), and the frequency turns out to be roughly inversely proportional to the rank. The Zipf's law formula:
f(r) ≈ C / r^s, where s ≈ 1
log f = log C − s · log r
The second line is the same formula after taking logarithms: on log(rank) vs log(frequency) axes it is a straight line with slope −s. So a Zipf's law calculator answers two simple questions: how close are your text's points to a straight line, and how close is that line's slope to −1. For the background of the law, see the Zipf's law article in our knowledge base.
One caveat: the ideal line is a model, not a target. In real texts the head of the distribution (the first 5–10 words) is usually a little flatter than the line, and the tail breaks into steps. That is expected and is what Mandelbrot's refined formula accounts for.
How to read the rank–frequency plot
The chart has three layers: blue dots are the words of your text, the orange dashed line is the ideal Zipf line with slope −1 drawn through the most frequent word, and the green line is the regression fitted to your text. Read it by zones:
- Head (ranks 1–10). With stop words kept, this is where “the”, “of”, “and”, “to”, “a” should sit. A noun from your target keyword among them is the first sign of over-optimization.
- Middle (ranks 10–200). Topical vocabulary. The dots should form a tight band along the green line. A dot clearly above the band is a word repeated more often than the text's own distribution suggests; such words are marked red.
- Tail. Horizontal “shelves” of words seen 2 or 3 times and a long shelf of words seen once (hapax legomena). Shelves exist because counts are integers, which is why one-off words are left out of the regression.
| What you see | What it usually means |
|---|---|
| Dots follow the line closely, slope near −1 | A typical distribution for a coherent text of decent length |
| A few dots in the head or middle well above the band | Specific words repeated: a key phrase, a brand name, a templated block |
| An almost flat head | A short text, a list, a table, or stop words removed |
| A steep drop after the first few words | A narrow vocabulary; the text circles around a couple of words |
| Wide scatter, low R² | Stitched-together fragments on different topics, lots of lists, code or numbers |
What slope is normal
A slope of −1 is a benchmark for large bodies of text. Short texts are almost always flatter: in 1,000–3,000 words most of the vocabulary only gets a chance to appear once or twice. Morphology matters too. The tool does not lemmatize, so “page”, “pages” and “page's” are counted as different words. English has few inflections, so an English article of a few thousand words often lands around −0.7 to −0.9; Russian, Ukrainian or Polish texts of the same size are flatter still because every case form is counted separately.
That is why the fit index is most useful for comparison rather than as a pass/fail grade. Compare texts in the same language and of similar length: your article before and after editing, or your page against the pages ranking above it.
Example: how keyword stuffing changes the distribution
An illustrative example. A 2,000-word article about web design has the phrase “cheap web design agency London” inserted into every third or fourth paragraph. In the original, the top ranks belong to “the”, “to”, “and”, “of”, and topical words start around rank 7–10. After the insertions, “design” and “web” climb to ranks 2–4 among the function words, while “cheap”, “agency” and “London” jump into the top 20. On the chart you see several red dots above the band near the head; in the table they carry the “above norm” mark and deviations from f₁/rank of several hundred percent.
Turn on “Remove stop words” and the picture gets sharper: function words drop out, and the words of the key phrase sit far above the regression line. To see the exact percentage of each repeat, including two- and three-word phrases, use the keyword density checker.
Using Zipf's law in SEO copywriting
- Pre-publication check. Run the finished text and look at the head of the distribution and the red dots. A keyword noun sitting among “the” and “of” is a cue to replace some repeats with synonyms and pronouns.
- Benchmark against the top results. Take 3–5 pages ranking for your query and compare slopes and highlighted words. If competitors keep the keyword in the middle of the distribution and yours is in the head, you have overdone it.
- Check after rewriting. After a rewrite, see whether the vocabulary got poorer: a steeper drop and a lower TTR at the same length point to recycled phrasing.
- Combine signals. Zipf shows the shape of the distribution, keyword density gives exact percentages, and the AI detector weighs many metrics together. Draw conclusions from all three.
Limitations
- Length. Below 300 words the estimates are unstable: two or three repeats shift the slope by tenths.
- Structure. Product lists, spec tables, code and FAQ blocks distort the distribution on their own. Analyze the main body text for a fair reading.
- Mixed languages. Foreign terms are counted like any other word and can skew the picture.
- Not a ranking factor. Search engines publish no “Zipf norm”. The law is a measuring tool; bending a text to fit the line makes no sense.
- Not proof of AI. Generated texts follow Zipf's law as well, and human texts break it because of genre. A deviation is a reason to reread the text, not a verdict.
RankBotAI — AI SEO Optimization for WordPress
RankBotAI AI plugin automatically finds and fixes SEO issues in WordPress products and posts — no manual editing.